OCR ScannedBook Pages
Turn scanned pages and screenshots into searchable text with local-first processing by default.
Local-First Processing
Works with Kindle Cloud Reader
No Desktop Software
Why Are Scanned Books So Hard to Search?
A scanned page is just an image until OCR turns it into real text.
Scanned book OCR converts page images into searchable, editable text. Upload your scans or page screenshots to textmuncher.com and Speed mode runs OCR locally in your browser with high accuracy. Optional Pro Quality mode sends hard-to-read pages for a cloud second pass, so leave it off for confidential scans.
Images Are Not Text
Scanned pages look readable, but search and copy do not work until OCR runs.
Cloud OCR Feels Risky
Many OCR sites require uploads, which is a bad fit for private research material.
Manual Transcription Drags
Typing passages from scans takes far longer than reading them.
Local OCR for Book Pages
Searchable Output
Create text you can search, quote, and reuse in notes or documents.
Private by Default
Speed mode processes pages in your browser instead of uploading them. Optional Pro Quality mode sends hard-to-read pages for a cloud second pass.
AI Ready
Paste extracted text into ChatGPT, Claude, or NotebookLM for summaries and questions.
How It Works
Three steps. No technical knowledge required.
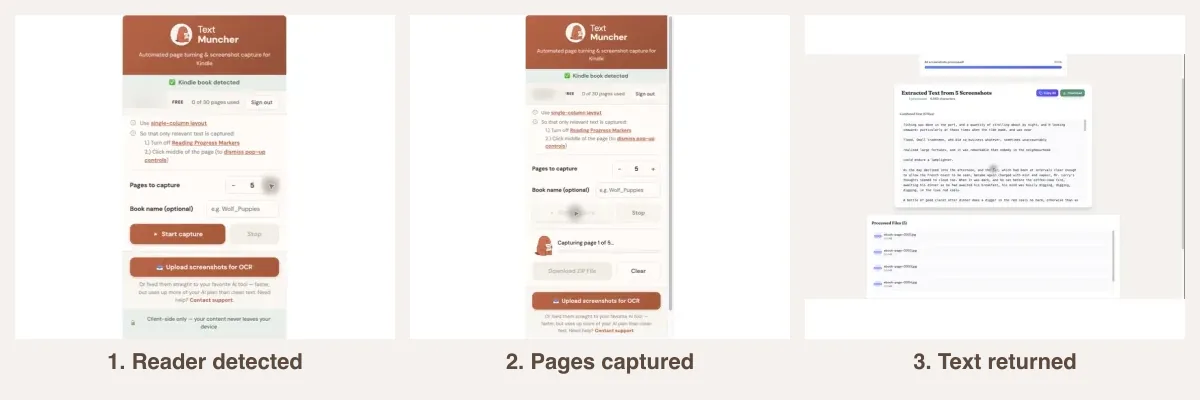
1. Open the Scan
Display the scanned book page in a browser-based reader or viewer.
2. Capture Pages
Use TextMuncher to OCR the pages you need.
3. Copy the Text
Paste searchable text into notes, documents, or AI tools.
screenshots versus extracted text why copy-paste gets blocked
Related Resources
The published OCR benchmark OCR eBook Screenshots PDF Textbook to Text Private eBook ExtractionFrequently Asked Questions
What is scanned book OCR?
It is the process of turning images of book pages into editable text. OCR reads the letters on the page and outputs copyable text.
Does OCR work on old or blurry scans?
It depends on scan quality. Clear, high-contrast pages work best. Crooked pages, decorative fonts, and heavy shadows may need cleanup.
Can I OCR pages from Internet Archive books?
The hands-free page-turning extension supports Kindle Cloud Reader only, so it will not auto-capture an Internet Archive reader. You can still OCR Internet Archive pages manually: take your own screenshots of the visible pages, then upload them to TextMuncher for text extraction. Always follow the platform terms and copyright rules for your use.
Is this different from PDF OCR?
The core idea is the same. TextMuncher is useful when the book is shown in a browser reader rather than available as a normal PDF file.
How can I get the most accurate OCR from a scan?
Feed it the cleanest image you can. Scan or photograph at a high resolution, keep the page flat and square to the camera, and aim for even lighting with strong contrast between the ink and the paper. Cropping out the surrounding desk or margins helps too. Clean, straight, high-contrast pages routinely hit the top of the accuracy range.
Does the output stay as editable text I can keep?
Yes. You get plain text back, which you can copy to the clipboard or download as a file and then edit, search, and store however you like. It is not a searchable-PDF layer baked back into the original scan; it is the raw text itself, which is more flexible for notes, quoting, version control, and feeding into AI tools.
Can it handle two-page spreads or multi-column scans?
It reads the text on the page, but complex layouts can interleave in the output, for example a two-column page whose lines get merged across columns. For the cleanest result, crop a spread into single pages and a multi-column page into one column at a time before running OCR. A little prep on tricky layouts saves cleanup later.
Are my scanned pages uploaded to a server?
By default, no. In Speed mode, recognition runs in your browser on your own device, so the scans never leave your machine during OCR. Optional Pro Quality mode sends hard-to-read pages for a cloud second pass. That is deliberately different from OCR websites that require you to upload every page; review your policy before using Quality mode with confidential documents.
Ready to OCR Book Pages?
Get TextMuncher Free30 free pages • No credit card • Cancel anytime